The Software Factory
This is how Fulltrace builds itself. A person keeps the roadmap and sets the order. An AI coding session does the building, one small planned piece of work at a time, and each piece is called a slice. Low and medium risk slices run unattended, day and night. Riskier slices and all design work run with a person in the session, and for risky work the rules recommend that a second AI is given the design and told to break it before anything is built. Every slice starts with a written plan and ends with a written closeout. The build log is what the factory produced, and the roadmap is where it is headed.
Unattended and Attended
Low and medium risk slices get built and shipped with nobody watching. A person puts rows in the queue in the chosen order and sets which Claude model the runner uses, with a cheaper one for low-risk rows. A session with nobody in it then works the queue one slice at a time, day and night. That run is called the chain. Each slice runs the whole protocol by itself, from kickoff through its named checks to closeout and a commit, and the next one starts straight after. Over 400 slices have shipped this way since 19 August. One run that started at midnight and ran for 18 hours took on 17 slices and shipped all 17.
A row qualifies when it is proposed, its prerequisites have shipped and its risk class is R3 or lower (the six classes are set out below). Rows for design or review work stay with a person. Each slice gets four hours a try and two tries. Uncommitted work left in the repo stops the run before it starts, and the first slice that fails outright stops the chain with everything left as it is.
A slice that meets a question only a person can answer is parked in an Awaiting ruling lane, and the chain moves on to the next row. Once it is ruled on, the row goes back in the queue. A slice that stops short for a reason the runner cannot name gets its second try on the next setting in a short fixed list of models.
Since 28 September the chain runs on a copy of the runner's code, taken when Start is pressed and kept outside the repo. A slice that changes the runner ships like any other, and the change takes effect at the next Start, which lists it first. A slice that touches the safety settings themselves, such as an assistant's permissions or the block on download commands, stops the chain until a person has reviewed it. The roadmap and the tests are not copied, so a slice can still change those.
The runner does not take a session's word for it. A slice counts as shipped only once its row is in the shipped register. Each slice commits its work on this machine as it goes.
The chain runs on a flat-rate Claude plan, so it has no dollar limit of its own. The cost shown on the board is what the same work would cost at API list prices. When the plan runs out of hours, the chain waits and checks again every 15 minutes, for up to six hours, and picks the same slice back up once the plan allows it. Waiting does not use one of its two tries.
With notifications switched on, a phone gets a heads-up when the work the chain may take is nearly gone, a count when closeout steps are confirmed, and the reason when the chain stops. A stop that needs a person is marked urgent. Every slice also records which model and effort it ran on, so what a run cost can be compared against what it was given to work with.
A Light on the Dark Factory
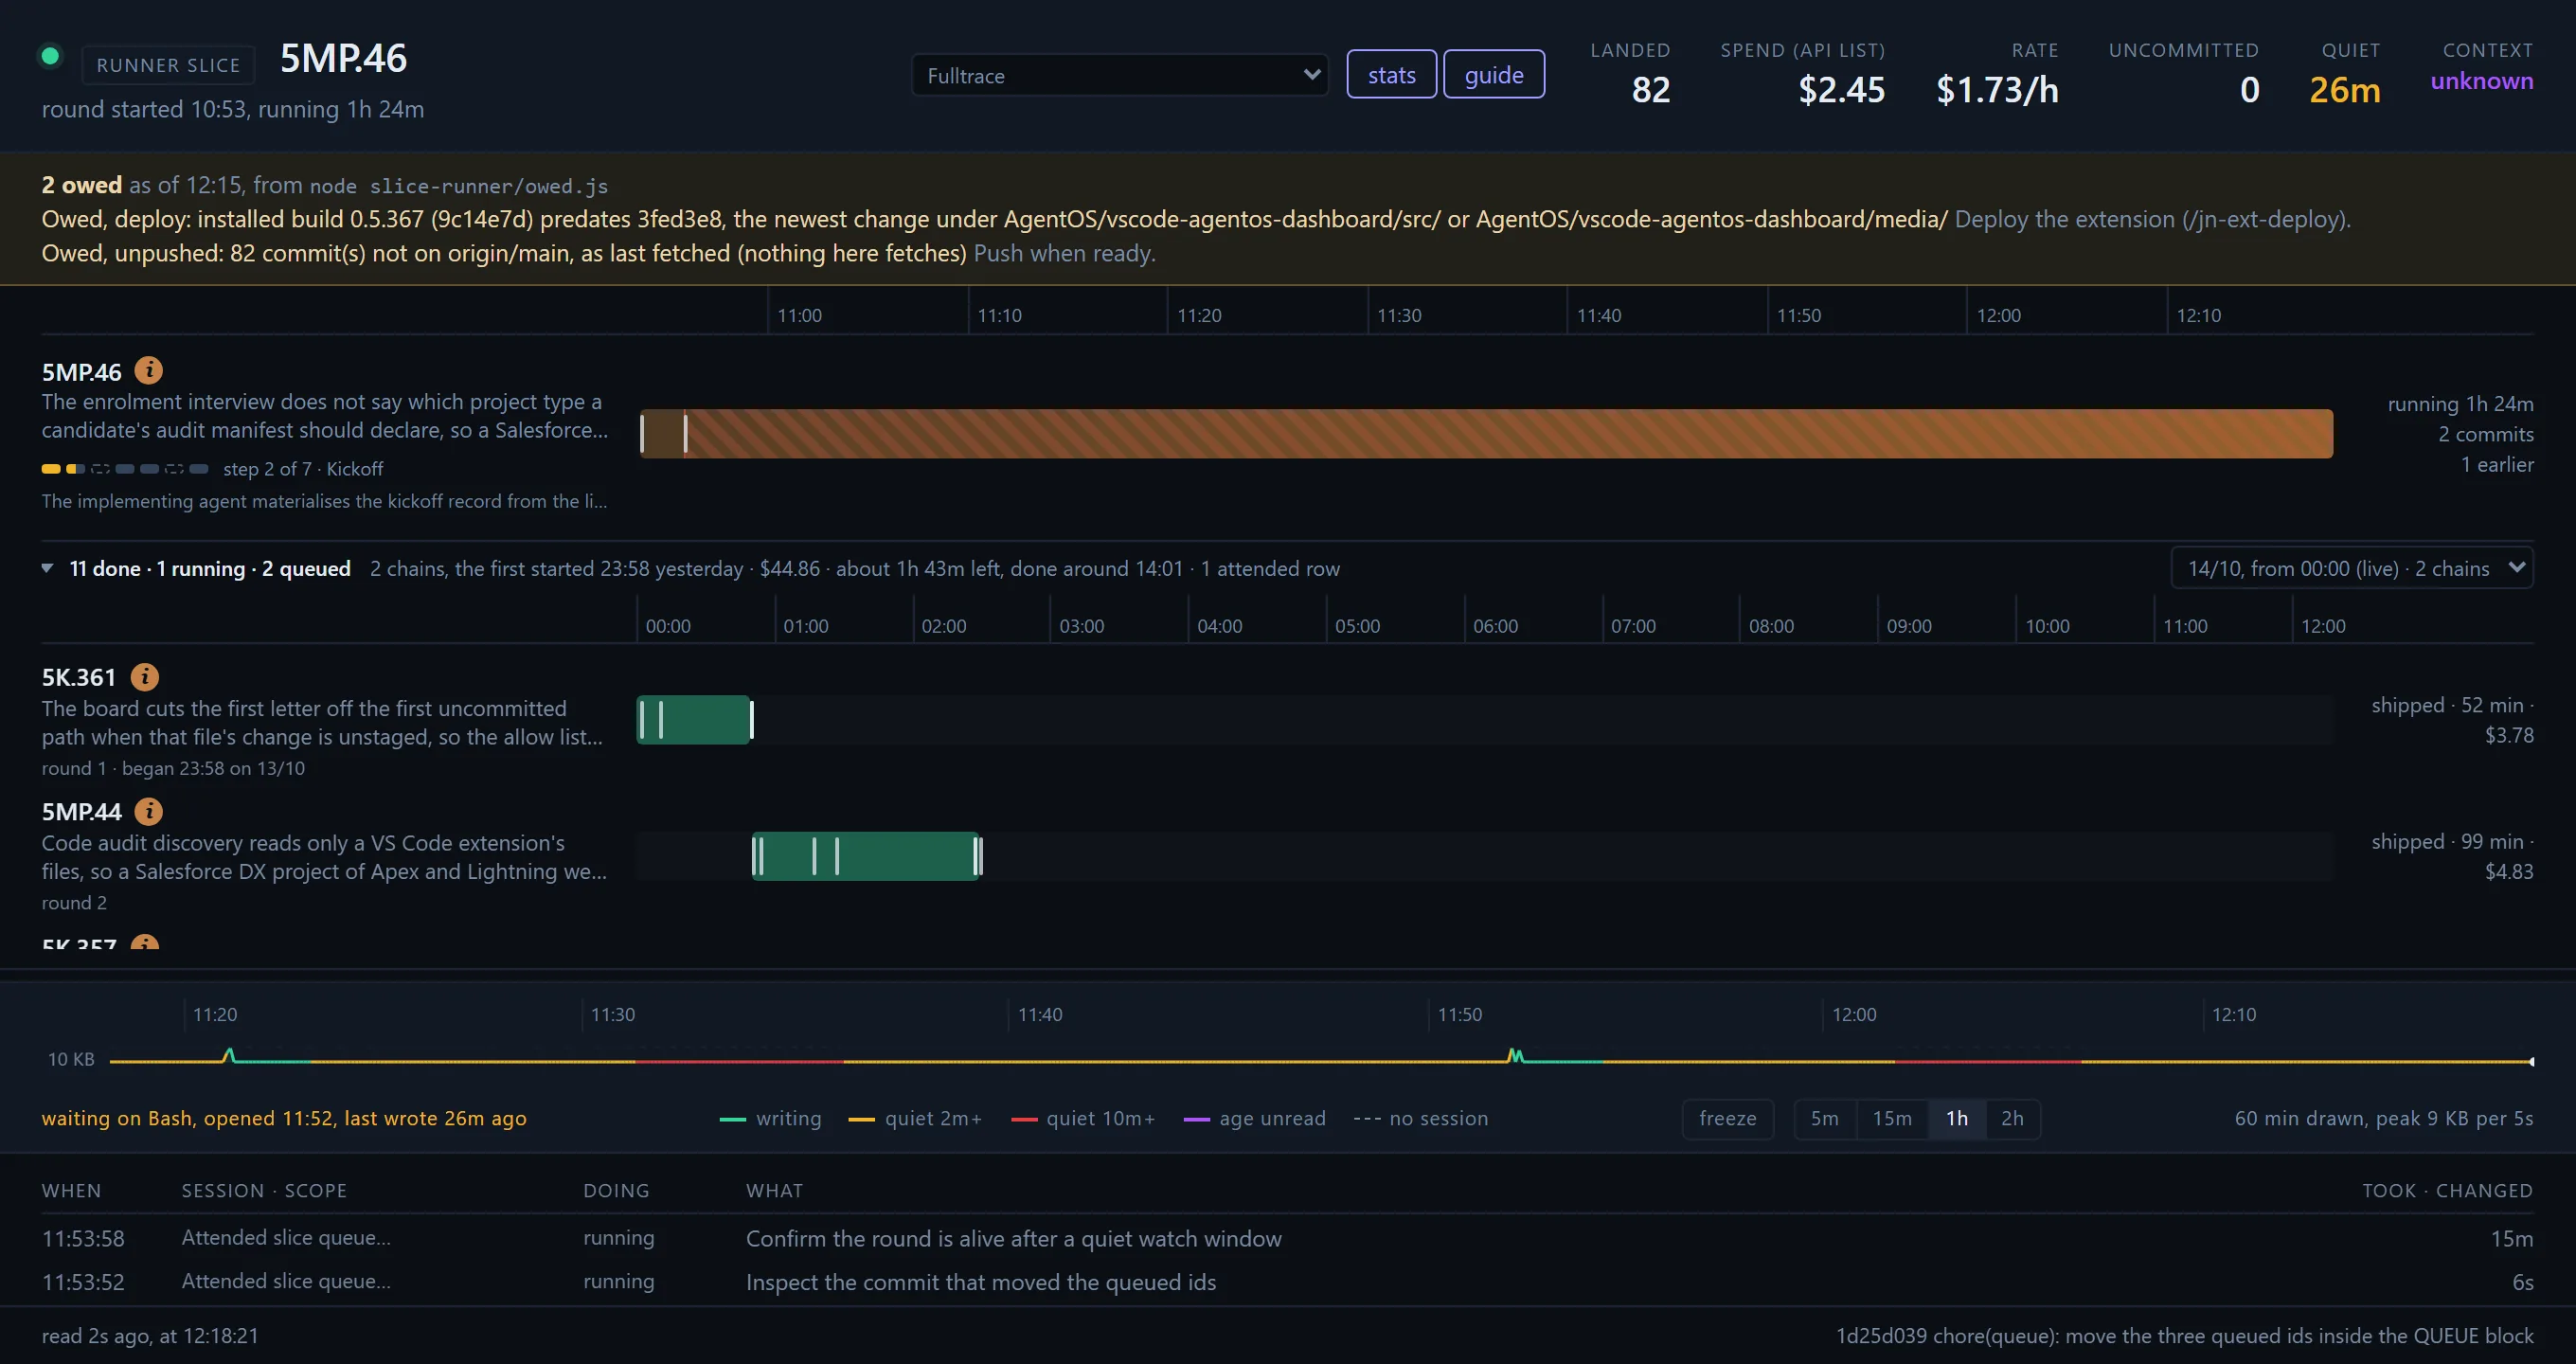
The factory runs dark, so Fulltrace has ways to switch the lights on. The board, a local page opened from Studio, shows the chain at work: the slice on the line, every round with its time and cost, and each commit as it lands. The stats page shows how much of the machine's working time the chain did, how long a shipped slice takes, and how much of that time goes to checks. And when a run ends, Fulltrace points at exactly what needs a person: the checks to click through and the decisions waiting.
Seven Steps for Every Slice
Every slice goes through the same seven steps, from a one-line docs fix to a new way of writing files. Only the design step changes with the risk.
Step 07 leads back to 01, because each closeout recommends the next slice.
Which slices run and in what order, approvals, and what happens to each review finding. Since August the AI settles routine bookkeeping questions itself, under a standing instruction, and each ruling is recorded as the AI's, made under that instruction. A question that needs a person stops the slice, and in the chain that slice is set aside so the queue keeps moving.
It writes the kickoff, builds the slice, runs the checks, writes the records and suggests the next step, with one clear recommendation. In the chain it also closes each slice and commits it.
Slices and Risk Classes
There is no sprint board and no ticket system. The unit of work is the slice: small enough to commit on its own, big enough to ship something real, with an ID that is never reused. The kickoff and closeout share that ID, so every slice sits between two written records. Each slice has a risk class, and the checks grow with the risk.
Design notes, plans and register changes. No code.
Code that calls no model, writes nothing and changes no screen.
New screens and read-only views. They display information and change nothing, and any new endpoint only reads.
Work that costs real money. The kickoff sets a spending limit before anything runs.
Anything that can change data or how the system behaves: writes, approvals, settings. Design first. Today these only run with a person in the session.
Opening the system to other machines or other people. A decision of its own, with everything R4 needs on top.
One File Steers the Work
The roadmap is a single markdown file with a hard rule: nothing longer than a paragraph goes in it. It changes only by editing rows and flipping statuses, and the long write-ups live in separate phase documents. That keeps it readable as a steering board.
Nineteen Standing Rules
These rules always apply: what can never widen, what never grants power, and what stays read-only. Each kickoff names the rules it touches by ID, and each closeout checks them. Since August each rule also has a record in code of how it is enforced: a guard that refuses, a test that fails, a checklist step, or nothing yet. Studio lists them under Config > Governance. In one sitting eighteen of them were ruled permanent and one temporary.
the_nineteen_invariantsexpand the full list
| ID | Invariant |
|---|---|
| G1 | No free models for reliability-critical audit, challenge, or apply runs. |
| G2 | No apply widening: structural, architectural, cross-surface, medium-confidence and ambiguous findings stay manual. |
| G3 | No portfolio-wide apply: every write is single-target, verifier-gated, build-gated, and ledgered. |
| G4 | No apply-write through the queue: approvals bind to an exact apply fingerprint, granted out of band. |
| G5 | The challenger stays advisory unless a separate policy decision says otherwise: a clear verdict never masks a failure. |
| G6 | The list of failure domains is not widened. It is the one list locked by the smoke tests. |
| G7 | After any server-side deploy, restart the server with the safe-restart wrapper before live validation. |
| G8 | No new platform code beyond accepted slices: new gateway endpoints are GET-only, and the few calls that change anything are named in the rule. |
| G9 | Config never grants authority: JSON cannot define new executable behaviour. |
| G10 | Secrets live in env or SecretStorage only: never in config, queues, ledgers, or reports. |
| G11 | Runtime artefacts are not source: no broad deletes over tracked report folders. |
| G12 | Every slice can be committed on its own, compiles, and passes the smoke tests where the server is touched. |
| G13 | Proposal-first: no model output is applied without deterministic validation and human review. |
| G14 | Screens that observe stay read-only, apart from confirmed actions the rule names one by one. By 9 October it had been amended eleven times, each time before any code. |
| G15 | A standing fence over hosted, multi-user, write-surface, and queued-apply expansions: opening it is its own decision. |
| G16 | Every grant record carries originating-surface and grantor-auth provenance from first write. |
| G17 | Decision-quality telemetry is descriptive only and never gates. |
| G18 | A design gate that refuses a real operator need must name the lawful alternative in the same document. |
| G19 | Bytes leave the machine only through registered egress seams. A message to a person needs a single-use grant minted by hand; social posting is never allowed. |
Written Records at Fixed Points
AI work rarely crashes. It trails off. So every slice produces written records at fixed points and in a fixed shape, which turns "done" into a claim that can be checked.
Written before work starts: what the slice will do, what is in and out of scope, the rules it must follow (quoted by ID), how success will be checked, the named checks, and a spending limit when models are involved. The closeout is judged against exactly this.
Short by rule, about 200 words: the outcome (shipped, partial or abandoned), the commits, what changed, and each check with its result. Two fields can never be left out. Manual check says what to click or run to see the result directly, and User docs says what changed in the user guide. A slice with nothing to show writes N/A and says why, and a slice that changed Studio's code cannot use N/A for Manual check. Since 8 September the manual check is written as a card: where to go, the steps to take, what a pass looks like and what a failure looks like.
Nine fixed steps: file the record in its phase document, update the phase index, the user guide, memory and the changelog, then move the row to the shipped register, tidy the queue, commit, restart the server if it changed, and check that the click pass can be built. The row moves near the end, because updating the docs is part of the slice. New rows are added the moment they exist, including every deferral. Since August a command drafts the four follow-up entries from the closeout record, and marks every sentence that needs a person.
The reviewer's verdict is pasted into the reviewed document word for word, and every finding gets a written decision: fold it in (with the edit), reject it (with the reason), or defer it (with the row that now owns it). The AI suggests each decision. A person makes it.
The Adversarial Review
For risky work, the rules recommend a review of the design before any code. The session that wrote the design starts a second AI with read-only access and one fixed instruction: break the design. It sees none of the first session's reasoning, so it cannot share its blind spots. Codex is the first choice. When Codex is out of quota, which the rules expect, the review steps down a short list: a manual upload to Microsoft Copilot, another vendor's command-line tool or a one-off script over OpenRouter, and last, a separate session from the same vendor. The switch is always recorded.
Every review returns a verdict (GO | CONDITIONAL-GO | NO-GO), findings ranked most severe first, answers to the document's open questions, and a list of what it tried and failed to break. The verdict does not decide on its own. A NO-GO whose findings are rejected can still ship, and the record says so. What the reviews have returned is on the codex page.
Three Backlogs
Not everything needs a risk class. Work waits in the backlog that matches how formal it needs to be.
The real work queue, inside the roadmap. Every row has an ID, a role, a risk class and its gates, and every slice starts from a row. The roadmap page shows it in full.
Small fixes to how Studio looks and behaves, with no ceremony: an entry goes in whenever something is spotted. Screenshots attach by file name, so an entry never needs editing to gain an image. Fixes launch from Build mode one at a time or as a batch.
Changes that never reached the docs, found by comparing the git log with the changelog, then worked as ordinary doc updates.
Build Mode in Studio
The factory is driven from Studio, the VSCode extension. Its Build mode has eight tabs (Slices, History, UI/UX, Inbox, Gates, Reports, Ideas and Films), and they read the live documents straight off disk.
The Slices tab kicks off a slice in a chosen coding assistant, which marks its row in progress. It also starts and stops the unattended runner, sets which model it uses and edits its queue. Build grants no new power, and the session still does the work. Most ticks on a slice's checklist are set by a file or a commit, so they show that a step really happened, and no tick can start or stop anything. The studio page covers each tab.
One Factory, Other Projects
For most of its life the factory built only Fulltrace. Since October it can work from another project's own roadmap. Three projects are enrolled: Fulltrace, the Salesforce Developer Tools extension, and this website, which has no roadmap of its own yet. One command gives a new project a starter roadmap. A project that plans its changes as OpenSpec files can bring each one in as a row that waits for a ruling, though none of the enrolled projects uses OpenSpec yet.
The first slice outside Fulltrace, and so far the only one, shipped on 5 October in the Developer Tools extension, in a run started by hand. The board, the stats page and Build mode in Studio can each show any enrolled project. Studio's Start button still runs Fulltrace only. A chain works one project for its whole length, so a run for another project has to be started by hand from the command line.
Why This Shape
Docs-only work moves at the speed of conversation. Work that spends money must set a limit first, and work that writes or grants power needs a written design before any code. The risk classes make that a rule, so it never rests on a judgement made in a hurry.
Every slice ends with a clear outcome and a recommended next step. The Manual check field means a claim can always be tested by hand, and an N/A has to come with a reason.
The documents hold the whole state of play. The AI's memory points at them and never replaces them. A new session on a new machine can pick up from the repo alone.
An author reviewing its own design shares its own blind spots. A fresh reviewer with a fixed prompt does not. Disagreements are recorded in plain view, and a person makes the call.